Skip to content
RunInfra
by RightNow
Model APIs
New
Pricing
Research
Resources
Contact
Dashboard
Sign in
Get started
Tag
Loading news
Tag
LLM
inference
Every RunInfra story filed under LLM inference.
All news
RunInfra
Research note
01
LLM inference
02
Quantization
03
FlashAttention
Category
Research note
August 3, 2026
Lossless Inference
RunInfra
August 2, 2026
The fastest way to serve DeepSeek V4 Flash
July 31, 2026
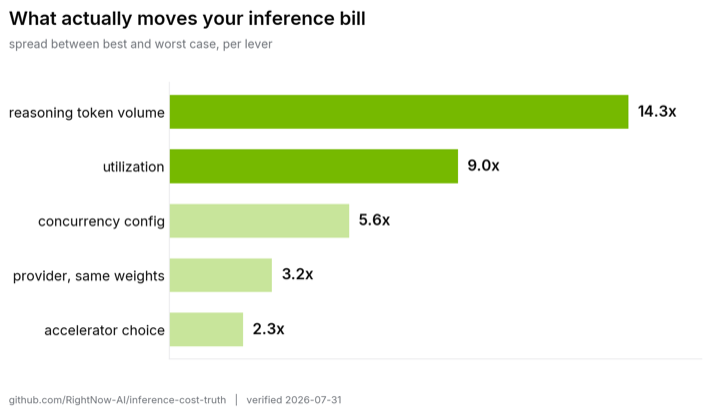
$0.09 and $290.12: What Actually Moves Your Inference Bill
RunInfra
July 30, 2026
Serving Kimi K3 on vLLM was hard. Here is what we measured.
RunInfra
Engineering
01
vLLM
02
SGLang
03
TensorRT-LLM
Category
Engineering
June 20, 2026
vLLM vs SGLang vs TensorRT-LLM: a serving benchmark
Start building on open
models
One API key for the OpenAI and Anthropic SDKs.
Get an API key
View pricing
TLS in transit, AES-256 at rest
Workspace isolation
No training on your data
SOC 2 Type II